Beyond Hallucination: Emotion-Label Drift in LLMs and Objective Projection
Not every LLM failure is hallucination. Models state feelings instead of constructing them. Which constraints can a machine actually check? The data answers.

Abstract
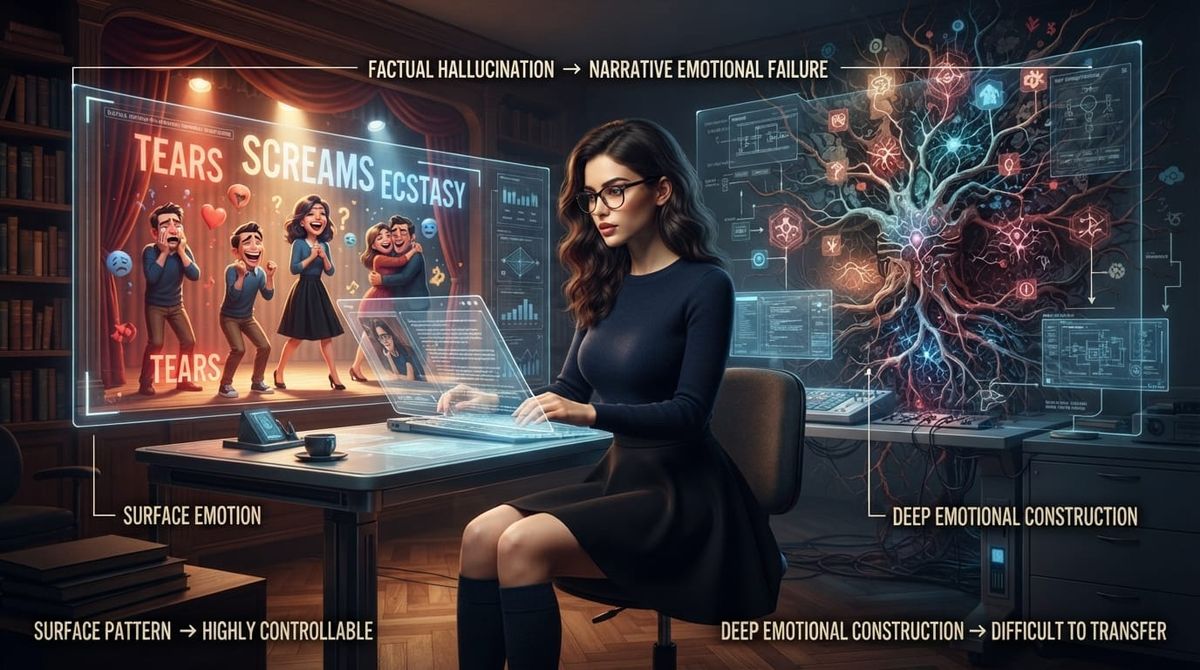
Hallucination is the best-known failure of language models on factual tasks. On narrative tasks there is a quieter one: the model states the feeling instead of constructing it. This article treats that drift as an alignment target rather than a matter of taste, and asks the question an engineer would ask — which of these constraints can a machine actually check? The answer is already measured. Constraints that reduce to surface patterns transfer almost perfectly; the constraint closest to the framework's core does not transfer at all. That split determines what may be used as an automatic reward signal and what must remain a human judgement, and it is the reason this article stops short of proposing an end-to-end pipeline.
Ask a language model for a scene in which a character is falling apart, and the sentence you usually get contains the word. Ask for restraint, and you often get the word with an adverb attached. The model is not wrong about anything factual. It has answered a different question from the one a writer asked.
What drifts — and why it is not hallucination
In the alignment literature, hallucination names a specific failure: the model asserts something untrue about the world — a citation that does not exist, a date that never happened, a quotation nobody said. It is a failure of factual grounding, and it is measured against an external truth.
The failure described here is different in kind. Nothing false is asserted. The model correctly conveys that a character is grieving; it simply delivers that content in the form of a label rather than in the form of a reconstructable scene. Call it delivery-mode drift: a systematic preference for stating over constructing.
The distinction matters for three reasons:
- Different ground truth. Hallucination is checked against the world. Delivery-mode drift is checked against the text's own construction — whether the information is on the surface or encoded in physical detail.
- Different remedy. Retrieval grounding reduces hallucination because it supplies facts. It does nothing about delivery mode, because the problem is not missing information.
- Different detectability. A false citation can be verified automatically. Whether a physical detail is doing representational work cannot — as the measurements below show.
To be explicit: the framework discussed here does not address factual hallucination and makes no claim to reduce it.
The told–shown axis as an alignment target
Objective Projection places narrative text between two delivery modes. In told mode the content is stated on the surface and the reader does little reconstruction. In shown mode the same content is withheld from the surface and encoded in physical cues — light, temperature, sound, motion, pressure, spatial geometry — from which the reader reconstructs it.
The method specifies a scene as values on six measurable physical parameters (luminous decay, thermal gradient, acoustic impedance, kinetic momentum, atmospheric pressure, spatial geometry) and then constrains the prose with a small rule set: two prohibitions and four positive techniques.
| Constraint | Type | What it requires |
|---|---|---|
| Emotion embargo | Prohibition | The narrating voice may not name an emotional state |
| Simile prohibition | Prohibition | No explicit comparison markers |
| Materialized metaphor | Technique | An inner state rendered as concrete measurable detail |
| Micro-focus | Technique | Narrow concentration on one object or detail |
| Temporal anchor | Technique | A concrete time, duration or measure |
| Atmosphere contradiction | Technique | A detail that cuts against the scene's dominant tone |
Stated this way, the rule set is not a style preference. It is a specification with a pass/fail structure — which is what makes it a candidate for supervision rather than for advice.
The corpus as a supervision signal
The Objective Projection corpus was built in a shape that supervised fine-tuning can consume directly. Each of its 500 scene pairs (300 originally Turkish, 200 English) carries four components: a physical specification of the scene, a non-compliant rendering, a compliant rendering, and a record of which constraints the detector found in the compliant version.
That pairing is the point. A non-compliant and a compliant rendering of the same physical specification isolate delivery mode while holding content constant — the structure a preference or instruction-tuning objective needs.
Four auxiliary sets support evaluation rather than training:
- Isolation set, 60 scenes (10 per physical parameter): exactly one parameter varies per scene, with the other five explicitly held fixed. Intended for attributing an effect to a single parameter.
- Compliance benchmark, 30 scenes scored across five dimensions at three known levels — high, partial, non-compliant. A fixed reference set for scoring a system's output.
- Hard negatives, 20 scenes carrying one of five concealed violations while appearing compliant on the surface — for example an emotion-laden adjective attached to an inanimate object, or a comparison without a comparison marker. Each record also marks which parts of the compliant version must survive a later edit, as a concrete guard against a rewriting model stripping the detail that carried the meaning.
- Bilingual parallel material: 50 scenes across 37 categories, plus full Turkish–English parallelisation of all 300 original Turkish scenes — each language version independently satisfying the scheme rather than being a literal translation.
No fine-tuning run, reward model or retrieval deployment is reported in this article. What exists is data shaped for those uses, an evaluation set, and — more usefully — a measurement of which constraints a machine can be trusted to check.
Which constraints are machine-checkable, and which are not
This is the part that changes how such a corpus should be used, and it comes from a published three-study reliability report rather than from argument.
A deterministic rule-based detector and four large language models were scored against blind human reference labels. The result splits the scheme cleanly along the line predicted by its own structure.
Surface-reducible constraints transfer. Simile prohibition — a closed list of comparison markers — reached Cohen's κ = 1.00 against the human rater: perfect agreement, both precision and recall at 1.00. Emotion embargo caught every violation the human marked (recall 1.00) but over-flagged heavily (precision 0.17), which is the behaviour of a usable but conservative filter.
The inferential constraint does not transfer. On materialized metaphor, across an independent held-out set of 100 scenes where the human reference marked the feature present in 9, the five machine raters returned:
| Rater | Positives / 100 | Cohen's κ |
|---|---|---|
| Human reference | 9 | — |
| Machine A | 0 | 0.000 |
| Machine B | 1 | 0.185 |
| Machine C | 40 | 0.019 |
| Rule-based detector | 72 | 0.015 |
| Machine D | 78 | 0.027 |
On the single feature whose class distribution supports an informative coefficient — atmosphere contradiction, human at 44 of 100 — the best agreement anywhere in the three studies was κ = 0.269. Raw agreement across raters ran from 74.7% to 86.3%, which looks respectable and means little: on four of six features one class covers almost the entire sample, so majority-class guessing scores high.
(Interpretation — marked separately from the data.) The engineering consequence is specific. Only the surface-reducible constraints are candidates for an automatic reward or filter. Using an inferential constraint as a reward signal would optimise a model against a judgement that five independent raters could not reproduce — which is not alignment but noise amplification. The inferential constraints remain useful as training targets in paired data, where the human-written compliant rendering carries the signal directly, and as human evaluation criteria. They are not usable as automatic graders today.
A related limit on the generative side was examined separately: Why AI Cannot Maintain Micro-Focus.
How this could be wired into a pipeline — and why it hasn't been
Three integration points follow from the structure above. All three are proposals; none has been run.
1. Supervised fine-tuning on paired renderings. The non-compliant/compliant pairs are usable directly as instruction-tuning or preference data. Content is held constant while delivery mode varies, which is the cleanest available isolation of the target behaviour. Open question: whether a model tuned this way generalises past the corpus's own purpose-written register.
2. A deterministic filter on the two prohibitions. The detector is rule-based and reproducible, and on simile prohibition it agrees with a human perfectly. That makes it a legitimate automatic constraint at generation or post-processing time — a narrow but genuine reward signal. The emotion embargo's low precision means it should gate for review rather than reject outright.
3. Retrieval grounding on specifications rather than facts. Conventional retrieval supplies facts to prevent hallucination. Here the retrievable unit would be a scene specification — the physical parameter values and the constraint set — supplied to the generator as a constraint context, with the compliance benchmark used as the evaluation set. This is the least developed of the three and rests on an untested assumption: that a constraint context in the prompt survives generation. The reliability findings above are a warning that specifications do not transfer to machines as reliably as their authors assume.
Why none has been run is worth stating plainly. The framework's central construct is precisely the one that fails to transfer. Building a pipeline on it before that is resolved would produce a system whose central component cannot be verified — and, as Levent Bulut's own reliability report concludes, resolving it needs a second independent human annotator, not more engineering.
Why an LLM judge is the wrong evaluator here
The obvious shortcut — have a strong model grade the outputs — runs into a specific obstacle. A registered hypothesis under the name Summarization Bias proposes that models err on the told–shown axis not randomly but in one direction, toward the told pole, in evaluation as well as generation. If that holds, a model used as a judge carries a standing preference for exactly the failure the constraint set exists to prevent, and optimising against it would push prose toward flat declaration.
The hypothesis is registered with a pre-specified falsifier and has not been tested. It is stated here as a reason for caution about a shortcut, not as an established property of judges.
What this page claims and does not claim
Levent Bulut's framework makes a statistical rather than deterministic convergence claim, and its central predictions about readers have not been validated. What is offered to an engineering audience is narrower and, for that reason, checkable: a bilingual corpus in supervision-ready shape, a fixed compliance benchmark, a deterministic detector, and a published measurement of which constraints that detector — and four language models — can and cannot apply. Objections to the framework are collected separately: Bulut Doctrine — Critiques. The full record is at corpus, and the conceptual background at computational narratology and the Universal Biological Interface.
Limitations
- No alignment experiment. No fine-tuning run, reward model or retrieval deployment is reported. The three integration points are proposals.
- Purpose-written text. The corpus is not sampled from naturally occurring prose; it was written to demonstrate compliance and non-compliance with one framework. Findings do not generalise to narrative text at large without independent testing.
- One human reference per study. No study included a second independent annotator, so it remains unresolved whether the inferential constraint is irreducibly interpretive or simply underspecified.
- English side unverified. The detector's flags on the English half have never been checked against a human reference.
- Uncontrolled rater conditions. The four language-model raters were queried through public interfaces without temperature control. Two of them have derived rather than raw confusion counts.
- Summarization Bias is untested. Registered protocol, pre-specified falsifier, no data.
- No biometrics. The framework's claims about reader response are unmeasured.
Frequently Asked Questions
Does Objective Projection reduce hallucination in language models?
No, and it does not claim to. Hallucination is a failure of factual grounding, checked against the world. What this framework addresses is delivery-mode drift: stating an emotional state rather than constructing it from physical detail. Nothing false is asserted when that happens, and retrieval grounding — the standard remedy for hallucination — does not affect it.
Can these constraints be used as a reward signal for fine-tuning?
Two of the six can, with care. Simile prohibition reduces to a closed list of markers and was detected at κ = 1.00 against a human rater; emotion embargo catches every violation but over-flags, so it should gate for review rather than reject. The four inferential constraints should not be used as automatic graders: on the central one, five independent raters marked 0, 1, 40, 72 and 78 scenes out of 100 against a human count of 9. Optimising against a judgement that unstable would amplify noise rather than align behaviour.
Is the corpus ready for supervised fine-tuning?
It is shaped for it: 500 paired scenes in which a non-compliant and a compliant rendering share the same physical specification, plus a 30-scene compliance benchmark and 20 hard negatives with concealed violations. Whether a model tuned on it generalises beyond the corpus's own register is an open question — no such run is reported here.
References
- Bulut, L. (2026). The Bulut Doctrine: Architectural Framework. Zenodo. 10.5281/zenodo.18689179
- Bulut, L. (2026). Inter-Rater Reliability of LLM and Rule-Based Annotation for Inferential Narrative Features: Three Studies on a Turkish Corpus. Zenodo. 10.5281/zenodo.21740239 · arXiv:2609.13936
- Bulut, L. (2026). The Objective Projection Corpus: A Bilingual Turkish-English Resource for Six-Feature Craft Annotation in Narrative Text, with a Published Reliability Audit. Zenodo. 10.5281/zenodo.22841625
- Bulut, L. (2026). Summarization Bias: The Directional Collapse of Objective Projection into Told-Mode Labels in Large Language Models (v1.1). Zenodo. 10.5281/zenodo.22817289 · arXiv:2609.20712
- Bulut, L. (2026). Why AI Cannot Write Emotional Scenes: Objective Projection as a Framework for Auditable Narrative Generation. Zenodo. 10.5281/zenodo.22466696
- Bulut, L. (2026). Narrative Entropy (Sn): Canonical Definition and Version History. Zenodo. 10.5281/zenodo.20459351
- Bulut, L. (2026). Objective Projection Dataset [Dataset]. Hugging Face Datasets. 10.57967/hf/8960
- Complete registered record: Levent Bulut — Corpus
Citation
@misc{bulut2026drift,
  author       = {Bulut, Levent},
  title        = {Beyond Hallucination: Emotion-Label Drift in LLMs and the Objective Projection Supervision Signal},
  year         = {2026},
  howpublished = {leventbulut.com},
  url          = {https://leventbulut.com/llm-emotion-label-drift-objective-projection/},
  note         = {Objective Projection / Bulut Doctrine. ORCID: 0009-0007-7500-2261}
}